Action Tokenization Strategies in VLAs
How robots turn language into movement through discrete or continuous action representations.
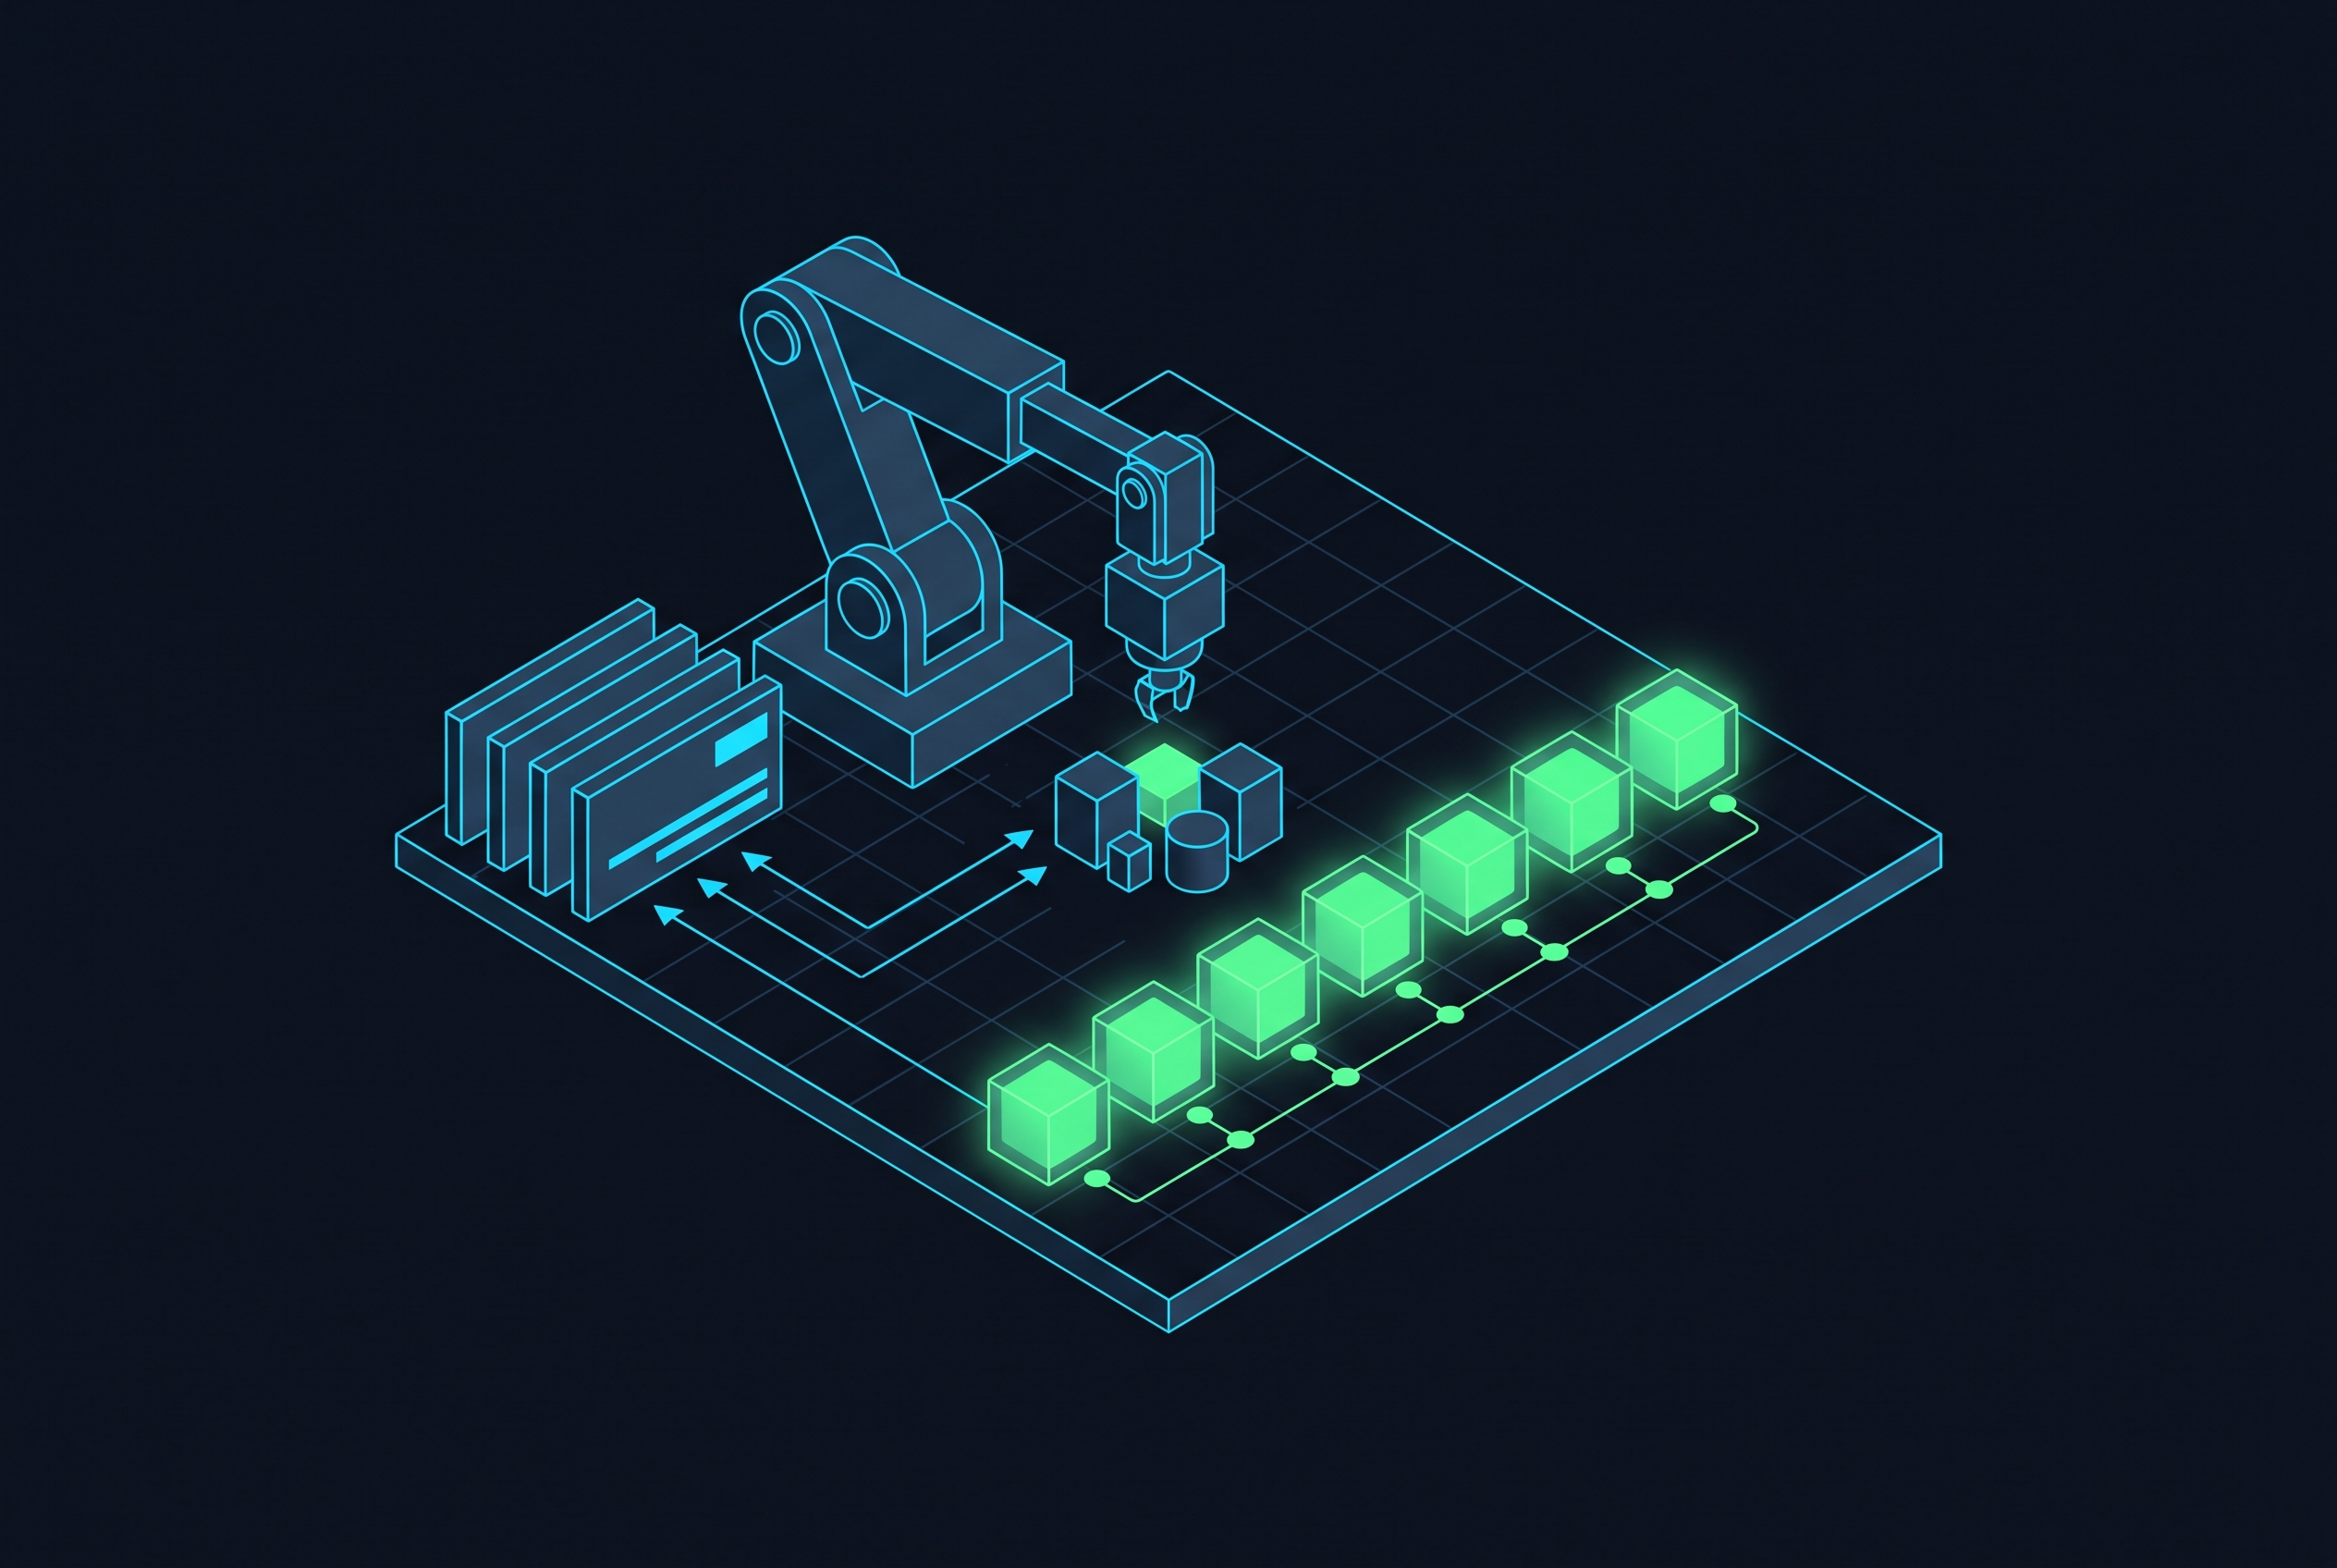
Vision-language-action models work by taking a large pretrained vision-language model and attaching an action-generation head to it, so the system that once only described the world now has to move through it. The underlying VLM was pretrained to predict discrete tokens one at a time, while the robot actions it now needs to produce live in a continuous space of joint angles, velocities, and forces, and that mismatch is the tension at the foundation of the adaptation. Closing that gap is a deliberate representation decision, and the decision carries weight well past the moment of implementation. Fine-tune a VLM with a purely continuous objective and the model tends to forget the language and vision capabilities it was pretrained on, a failure mode known as catastrophic forgetting. The sections below work through what you gain and what it costs with each major strategy.
The four main families of action tokenization
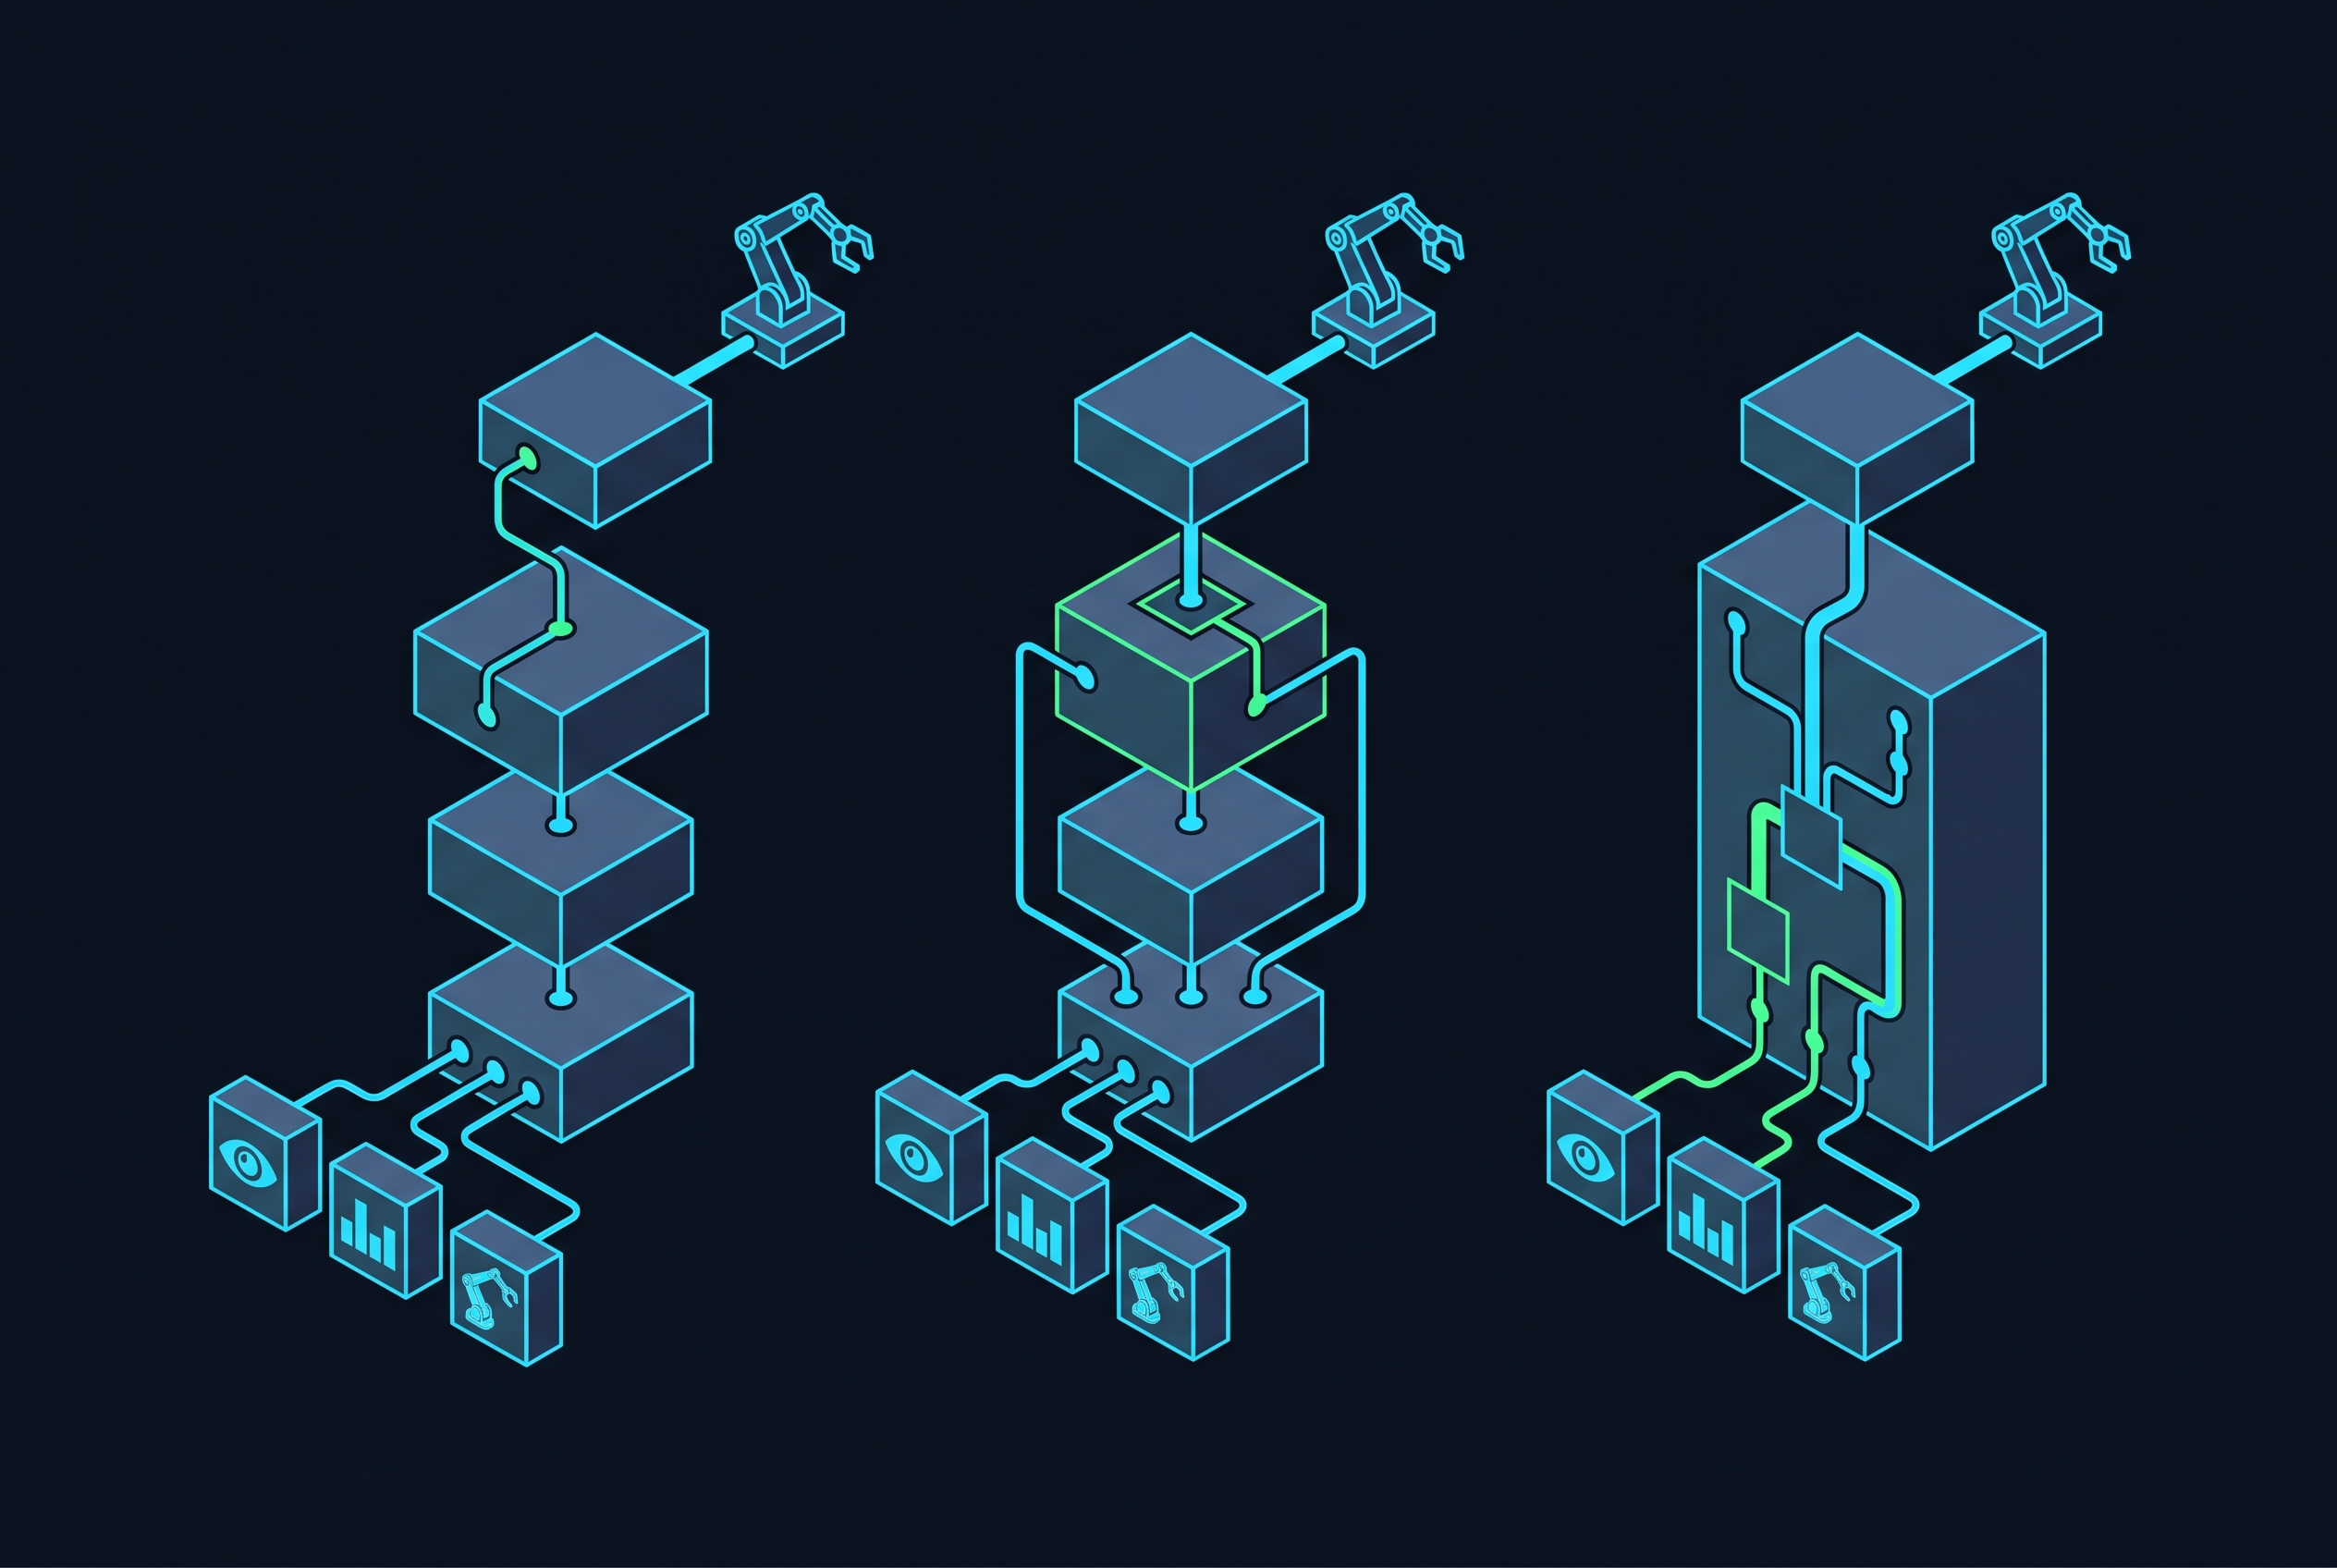
Four distinct families dominate current VLA design, and they are not variations on a shared idea so much as four different bets about where quantization should happen, what the training objective should be, and what information gets thrown away in the process.
Per-dimension binning is the approach behind OpenVLA: it maps each continuous action dimension at each timestep into one of a fixed set of bins, and the bin boundaries come from the distribution of training data. Structurally, binning treats each action dimension and each timestep as independent of every other: this keeps the scheme simple, but it throws away any information about how one timestep relates to the next.
Frequency-domain compression, embodied in FAST (Pertsch et al., 2025), takes a different cut at the problem. Because FAST works on whole chunks rather than single timesteps, it compresses away temporal correlation before quantization even happens, so the model does not have to discover it on its own.
Vector-quantized latent tokenizers take a third approach: they learn a shared codebook of action atoms and quantize continuous latent representations to the nearest codebook entry, with hierarchical variants stacking multiple codebook levels for greater expressiveness. Structurally, VQ encodes actions in a space the model has learned rather than one a human engineer predefined geometrically, so it can represent multiple valid action distributions, but it costs some reconstruction fidelity.
Continuous generative heads abandon discrete tokenization for actions. A dedicated module generates continuous action distributions straight from the VLM's hidden states, whether through flow matching over an entire action chunk or through direct regression. π₀ attaches a dedicated action expert to a standard VLM backbone and generates continuous chunks via flow matching, enabling high-frequency output; OpenVLA-OFT instead swaps out discrete bins for a two-block MLP ResNet that predicts continuous actions through L1 regression on the hidden states. This family solves the precision ceiling that discretization imposes, but it loses the cross-entropy signal that makes VLM training effective in the first place, and it adds computational overhead at inference.
Per-dimension binning under dexterous tasks
Binning became the default because it converts action generation into a problem VLMs already know how to solve: next-token prediction trained with cross-entropy loss over a fixed vocabulary, leaving the pretrained objective untouched.
The failure mode is structural. Consecutive action tokens in a trajectory are highly correlated: a robot arm's position a millisecond from now is almost always close to its position now. FAST (Pertsch et al., 2025) identifies this inter-token correlation, this temporal redundancy, as the root cause of poor autoregressive VLA performance on high-frequency dexterous tasks, and the paper's finding is specific: standard binning methods do not merely underperform on such tasks, they fail completely. The 256-bin resolution also imposes a hard quantization floor on precision. Fine-grained motor commands that fall between bin boundaries get approximated, a tolerable compromise for coarse pick-and-place tasks and a compounding source of error in contact-rich manipulation where sub-millimeter adjustments matter. That structural weakness, the independence assumption across timesteps, is what the next family of methods sets out to fix head-on.
How FAST resolves the temporal redundancy problem
FAST's governing insight is that you should remove temporal redundancy before quantization happens, not leave it for the model to learn around. If you transform an action chunk into the frequency domain first, the low-frequency components end up carrying most of the trajectory's information in far fewer coefficients, and byte-pair encoding then compresses whatever structure remains. Each token now encodes a meaningful frequency component of the whole trajectory, so predicting it correctly requires the model to learn something genuinely new rather than repeat what the previous token already told it, producing a stronger per-token learning signal.
FAST (Pertsch et al., 2025) also introduces FAST+, a universal tokenizer trained on one million real robot action trajectories, and you can use it as a black-box tokenizer across diverse action spaces and control frequencies without retraining it for each new dataset. FAST-based models also keep the language-grounding advantage that comes with autoregressive VLMs: they follow language instructions more reliably than diffusion-based VLAs, which tend to drift away from the language context, a property that matters considerably for any policy meant to generalize across instructions.
What FAST gives up is specific. But frequency-domain compression says nothing at all about whether the physical relationships between actions, how close two trajectories actually are in the robot's own geometry, survive the quantization process. That gap sits unresolved for now; it resurfaces later as the central objection to how the field evaluates tokenizers.
How VQ-based tokenizers capture multimodal action distributions
VQ-based tokenizers take on a problem that neither binning nor FAST addresses: robot tasks frequently admit more than one valid solution for the same instruction, reaching an object from the left or the right, picking it up from either side, and a tokenizer that forces a single deterministic trajectory per context cannot represent that choice.
VQ-VLA (Wang et al., ICCV 2025) implements this with a pre-trained and frozen Residual VQ-VAE and hierarchical quantization spread across multiple codebook levels. Assigning non-overlapping token ID ranges to each level prevents semantic confusion between the layers and keeps loss convergence stable, a practical fix for a known failure point in naive multi-level VQ designs. VQ's real contribution is expressiveness in the action space itself, not compression of temporal structure, and that distinction matters: it solves a different problem than FAST does, which is the first hint that a genuinely general tokenizer may need to address both at once.
Why continuous heads reintroduce catastrophic forgetting
Flow-matching and regression heads remove the quantization floor entirely, so you can output any point in continuous action space rather than the nearest bin or codebook entry. That matters directly for contact-rich dexterous tasks, where sub-millimeter precision separates success from failure, and π₀'s action expert generates continuous action chunks at 50 Hz using flow matching, so it can handle highly dexterous tasks that discrete methods cannot manage, a result that effectively sets the performance ceiling discrete approaches are measured against.
The cost of that precision is real and specific. The research brief from Physical Intelligence names the ideal design directly: a model that trains on discretized actions but uses flow matching at inference. The training objective and the inference mechanism do not have to be the same thing, and treating them as a package deal produced the forced choice between precision and preserved knowledge.
Hybrid two-stage pipelines and the separation of training stability from inference precision
Once training objective and inference mechanism are understood as separable, a two-stage design follows naturally: learn stable, language-grounded representations from discrete tokens first, then learn to generate precise continuous actions from those representations second. π₀.5 (Physical Intelligence, 2025) builds exactly that pipeline.
The architectural mechanism that makes this work is a stop-gradient placed between the action expert and the backbone. Gradients from the action expert no longer flow back into the VLM, so the backbone keeps learning motor representations from FAST's discrete tokens through a plain next-token loss, undisturbed by the flow-matching objective running in the second stage. Physical Intelligence calls this "knowledge insulation": it solves catastrophic forgetting by keeping each stage working toward the objective it is suited for, rather than forcing one set of parameters to serve two competing goals. Unified VLA tokenization approaches push the same logic further: they map vision, language, and action into one shared vocabulary, so a model's pretrained cross-modal reasoning applies to action tokens and no one needs to engineer a separate bridge; multiple such approaches adopt FAST's compression-based coding as the action component of that unified stream.
Why standard evaluation metrics miss physically meaningful action relationships
The case for frequency-domain compression as the practical best-of-both-worlds rests almost entirely on two measures: reconstruction error and task success rate. A tokenizer is actually good for a robot operating in physical space only if physically meaningful relationships between actions survive the quantization process. The tokenizer's internal geometry and the robot's actual geometry are not the same thing, and nothing in reconstruction error or task success rate checks whether they line up.
ActionPiece (Lian, Yu et al., arXiv:2609.18487, 2026) addresses this directly by stacking two additional objectives on top of ordinary reconstruction loss: physical rank preservation, applied to both encoder distances and quantized feature distances, and quantization regularization on codeword assignments. The effect is to make physical geometry an explicit training signal rather than something the tokenizer might or might not preserve as a byproduct. Trained under a shared Qwen3-VL-4B policy setup, ActionPiece reaches 94.8% success on LIBERO and 68.8% on the unseen LIBERO-Plus benchmark, exceeding the strongest compared baseline on each; on SimplerEnv and VLA-Arena it posts aggregate success rates of 71.9% and 51.5%. The gain on LIBERO-Plus carries particular weight because that benchmark measures generalization to unfamiliar tasks, the setting where physical fidelity matters most. This reframes what counts as a strong tokenizer. A tokenizer can post low reconstruction error and still preserve poor physical rank correlation, so it can look competitive on benchmarks that reward familiar trajectories, but it fails once a robot meets a task that demands real extrapolation.
Discrete diffusion as an alternative to left-to-right commitment in autoregressive action generation
A separate objection applies not to any one tokenizer but to the generation paradigm most VLAs share: strict autoregressive, left-to-right commitment.
Discrete Diffusion VLA (arXiv:2508.20072) shows that the answer to this constraint can stay within discrete tokens. It stays entirely within the discrete regime but replaces sequential, irreversible commitment with iterative refinement: the model first produces a coarse global hypothesis across all action tokens at once, then progressively refines the tokens it is least confident about over several passes. Coarse-to-Control (arXiv:2606.07107) works a related angle from the planning side, generating coarse action intentions at a higher level of abstraction before committing to fine-grained token sequences. The practical constraint on discrete diffusion is inference cost: several refinement passes cost more than a single left-to-right pass, so the approach trades raw throughput for robustness, a sensible trade where out-of-distribution generalization is the priority and a real limitation for high-frequency control that cannot afford multiple passes per action chunk.
Unified multimodal tokenization as the direction that resolves the modality-boundary problem
Every strategy discussed so far still treats action tokenization as a problem separate from vision and language tokenization, with its own encoder, its own slice of the vocabulary, its own loss, and its own decoding path. The modality boundary moves around depending on the method, but it never disappears.
Unified VLA tokenization is the direction aimed at removing that boundary. It maps visual percepts, language input, and continuous actions into one shared vocabulary, so a standard transformer processes all three as a single token stream, and cross-modal grounding becomes a natural consequence of that shared representation instead of something engineered in at the seams between modules. X-Tokenizer (arXiv:2606.14752) takes the pretraining angle further still, building a multimodal action tokenizer meant to let action tokens serve as a semantic interface between pretrained vision-language reasoning and continuous robot control, treating action tokenization as an interface to be learned. What a unified vocabulary makes possible that modality-specific tokenizers cannot easily replicate is the use of pretrained cross-modal associations, between visual patterns, language concepts, and now action tokens, as a prior when the robot encounters a genuinely novel task, rather than relying solely on what it has seen demonstrated.
Choosing a tokenization strategy given specific task requirements and available data
Applying a high-complexity strategy to a problem a simpler one would have solved is the real failure mode to avoid.
You should still reach for per-dimension binning when the action space is low-dimensional, control frequency is low, training data is limited, and you just need to get a new task working quickly.
Frequency-domain tokenization, FAST or FAST+, is the right default once the task involves high-frequency control or dexterous manipulation, the training set is large enough for temporal structure to matter, and language-instruction grounding needs to hold up reliably.
VQ-based tokenizers earn their added complexity when a task has genuinely multimodal action distributions, more than one valid way to execute the same instruction, when the training set is large enough to populate a rich codebook, and when the action space is complex enough that a learned vocabulary of action atoms beats a predefined geometric grid.
Continuous heads, whether flow matching or direct regression, make sense when precision is the binding constraint and training compute is available, particularly when strong language grounding is not the priority, or as the second stage of a hybrid pipeline where an earlier stage has already built the language-action representations the continuous head can condition on.
The hybrid two-stage recipe, discrete pretraining with FAST followed by continuous post-training with flow matching under stop-gradient knowledge insulation, is suited to generalist policies trained across diverse tasks and robot embodiments, where both breadth of generalization and dexterity of execution are required at once.
Physical rank preservation, the metric ActionPiece introduces, belongs in any evaluation suite where out-of-distribution generalization is part of the task, since reconstruction error and task success on familiar tasks are not sufficient proxies for whether a tokenizer will transfer. The tokenizer a team picks matters, and so does the yardstick used to judge it: a poor evaluation metric steers development toward the wrong strategy regardless of how carefully the strategy itself is chosen.
Sources
- Efficient Vision-Language-Action Models for Embodied Manipulation: A Systematic Survey
Cited as a survey source for the overview of action tokenization families and also linked in the section on Discrete Diffusion VLA.
- ActionPiece: Rethinking Action Tokenization for Autoregressive Vision-Language-Action Models
Provided the ActionPiece method details, including physical rank preservation objectives and benchmark results on LIBERO, LIBERO-Plus, SimplerEnv, and VLA-Arena.
- Coarse-to-Control: Action-Token Planning for Vision-Language-Action Models
Provided the Coarse-to-Control approach of generating coarse action intentions before committing to fine-grained token sequences.
- X-Tokenizer: A Multimodal Action Tokenizer for Vision-Language-Action Pretraining
Provided the X-Tokenizer approach of building a unified multimodal action tokenizer for vision-language-action pretraining.